How to Benchmark AI Recommendations Without Fooling Yourself
A fair AI recommendation check answers one narrow question. Under a fixed set of realistic buyer-intent questions, did this assistant surface or select the business at that point in time? To answer it fairly, keep the questions the same each round, save the evidence, and treat each result as a dated observation, not a ranking.
A recommendation check should not claim a permanent ranking. It should not imitate every consumer product experience. It should not use questions designed to mention the target by name. A useful check creates a comparable observation, preserves the evidence, and tells the owner what can be improved without pretending to control the model.
A recommendation check is a method you run yourself. Runexus does not run these checks today. The free quick snapshot scores readiness from your site and public sources. It does not ask an assistant whether it recommends you.
A fair recommendation check requires discipline in question design, execution, classification, and reporting.
How do I test whether AI recommends my business?
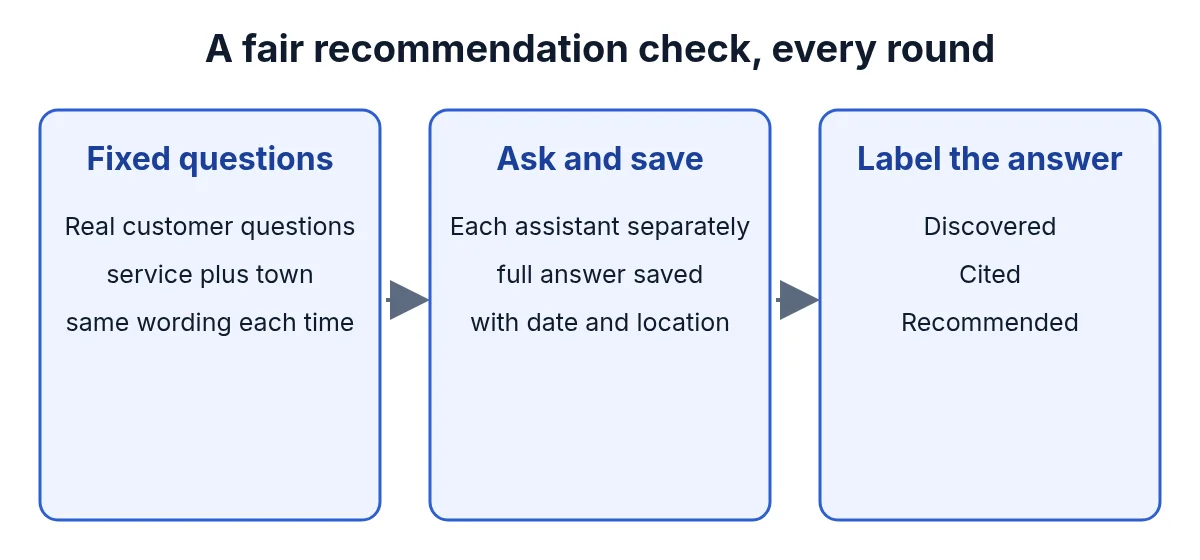
Write a small fixed set of real customer questions (service plus town), ask them the same way each time, and record the full answers with the date and location.
More questions do not automatically produce more truth. A large uncontrolled set increases the chance that changing wording drives the result.
Five buyer-intent families are enough for a focused check:
- Broad recommendation in the category.
- Primary-service recommendation.
- Problem-and-solution recommendation.
- Shortlist or comparison.
- Direct high-intent selection.
The wording should come from the approved business category, offering, and market. Local businesses may include real service geography. Online businesses should not receive invented phrases such as "in Online only." The business name and domain stay out of the question; putting them in would turn discovery into a leading test.
Once written, freeze the questions. Change them only when you start a new round you can compare on purpose.
Define the questions before you test. A local business usually needs a compact set covering broad category intent, a high-value service, a supported specialty, geographic intent at the city or neighborhood level, and a direct "who do you recommend" request. Five to ten questions are usually enough. The owner should review them so the set reflects the customers the business actually wants to serve.
How big should each test round be?
Each question should be one concise request, asked the same way, with the same location context. Record the assistant, the exact question, the location, and the time. Without that information, later comparisons become anecdotes.
"Best pizza near me" is not reproducible unless you record what "near me" meant. A service-area question should state the intended city or region. A multi-location business should measure locations separately rather than treating one answer as the brand's universal result.
If a try fails, times out, or returns too little to judge, mark it unavailable. Unavailable is not a negative score. It is a missing observation.
How should I label what each test found?
Each completed response should retain three labels, grounded in the captured answer:
- Discovered: the exact business appeared meaningfully.
- Cited: the answer supplied actual source metadata tied to the business or relevant evidence.
- Recommended: the answer explicitly selected or shortlisted the exact business.
A source name or URL must never be invented. A mention is not promoted to a recommendation because it sounds favorable.
Those three states diagnose different parts of the evidence journey: finding a business, citing a source, and recommending it.
If one AI assistant recommends me, will the others?
Not necessarily. Each assistant searches and answers in its own way, so one result is no proof of another; record and compare them separately.
A result from one assistant is not proof of another. Combining every assistant into one opaque number hides the useful information: where the business appears, where it does not, and which sources each answer relied on.
When an answer supplies citations, store them. They help explain why a business was selected and which public sources are shaping the answer. Competitor appearances are useful if you handle them carefully. Don't copy a competitor's claims. Look at what their public evidence has that yours lacks, such as clearer location data, more relevant reviews, a sharper specialty, a better-matched category or a trusted third-party source.
The owner-facing result can stay compact. Selected means the business was recommended or shortlisted in at least one valid question. Visible, not selected means the questions completed and the business appeared or was cited, but was never recommended. Not surfaced means the questions completed and the business did not meaningfully appear. Unavailable means the round was insufficient to judge. A failed try must never be recorded as "not surfaced."
What records should I keep from each round?
Store the exact question set, the assistant, the labels, the captured sources, the completion state, and the timestamp. Later rounds create new records instead of rewriting old ones.
Keeping a dated record of every round lets a business compare observations responsibly. "Selected in one of five questions in August and three of five in September" is a historical description, not proof of a permanent ranking gain. The evidence can then be inspected for legitimate changes in business truth, authority, or intent fit.
The same discipline applies to the dated findings in this article.
What should I do after testing AI recommendations?
Pick the one change the evidence supports best, make it, and retest with the same questions after it's live.
If the business was not discovered, inspect the domain, category, entity, and market language. If it was visible but not selected, compare the cited evidence and fit for the buyer's request. If it was selected, preserve the supporting facts and sources rather than inventing unnecessary work. If the round was unavailable, retry before drawing a market conclusion.
The action should remain legitimate: reconcile conflicting business facts, improve an approved service description, correct canonical links, update real profiles, make valid credentials easier to verify, or request honest customer reviews through normal channels. Bought links, fake reviews, fabricated profiles, and questions engineered to force selection do not create trustworthy evidence.
Compare periods, not isolated prompts. One improved response does not prove a permanent ranking increase. Repeated improvement across several relevant questions and dates is stronger evidence that the public field is becoming clearer.
What should I measure, and what can't a test promise?
Recommendation checks measure what happened when you asked any consumer assistant on that date. They do not guarantee what any consumer assistant will do next week. They also do not replace the ongoing work of maintaining business truth, independent corroboration, and machine-readable access.
The limits of a recommendation check are a strength. A careful record gives the owner a repeatable observation instead of a marketing claim. The public quick snapshot covers controllable website signals and a bounded look at public corroboration. It does not run these recommendation checks. Use the same questions again after a real change, and ask what the answer actually showed and which legitimate improvement should happen next.
Is an AI visibility score enough to know what to fix?
No. A score is a summary; to know what to fix you need the findings behind it: what was checked, when, and what was found.
How do I tell if my AI readiness actually improved?
Look at which specific findings changed between two dated snapshots, not just whether the number went up.
Does a missing result mean my business failed the check?
No. A check that couldn't run is unavailable, not a zero, and should be retried rather than counted against you.
Sources
- Maps User Generated Content Policy Help, "Prohibited & restricted content"
- Federal Register, "Trade Regulation Rule on the Use of Consumer Reviews and Testimonials"
- Google Search Central, "Spam Policies for Google Web Search"